When an AI provider hits its limits, switching to a backup sounds straightforward. But for an AI agent, that switch can mean processing the same context all over again, adding latency, cost, and pressure on the next provider.
With peak traffic above a billion tokens per minute, we needed to handle provider failures without wasting that capacity. This is the problem behind Lovable’s LLM provider load balancer.
Load balancing in agent-based systems is not just about finding any provider with spare capacity. Providers are not interchangeable: we may prefer one model because it's smarter, or a provider because it offers faster inference for the same model. And because agent requests can reuse a provider's cached prompt prefix, switching providers can require reprocessing that context, increasing latency and cost.
Prompt caching and the need for provider load balancing
We have capacity across a number of model providers (e.g., Anthropic, Vertex, Bedrock), so that if one provider goes down, we can fall back to the others to reduce disruption for users. Naively, we could create a ranked list: send the primary provider all the traffic it can handle, then spill over to the second, and so on.
However, consider a scenario in which our primary choice is returning rate limits, so some requests go through, while others fall back to the second choice. This is terrible for prompt caching.
Prompt caching improves the speed and costs of working agents by letting subsequent calls reuse earlier prompts and context. We leverage it a lot at Lovable, because our agent typically does some exploration before starting code generation, retrieving context and state on initial calls.
Prompt caching relies on requests reaching a provider with the relevant prefix cached. When requests for the same project are split across providers, cache misses can require the full context to be reprocessed.
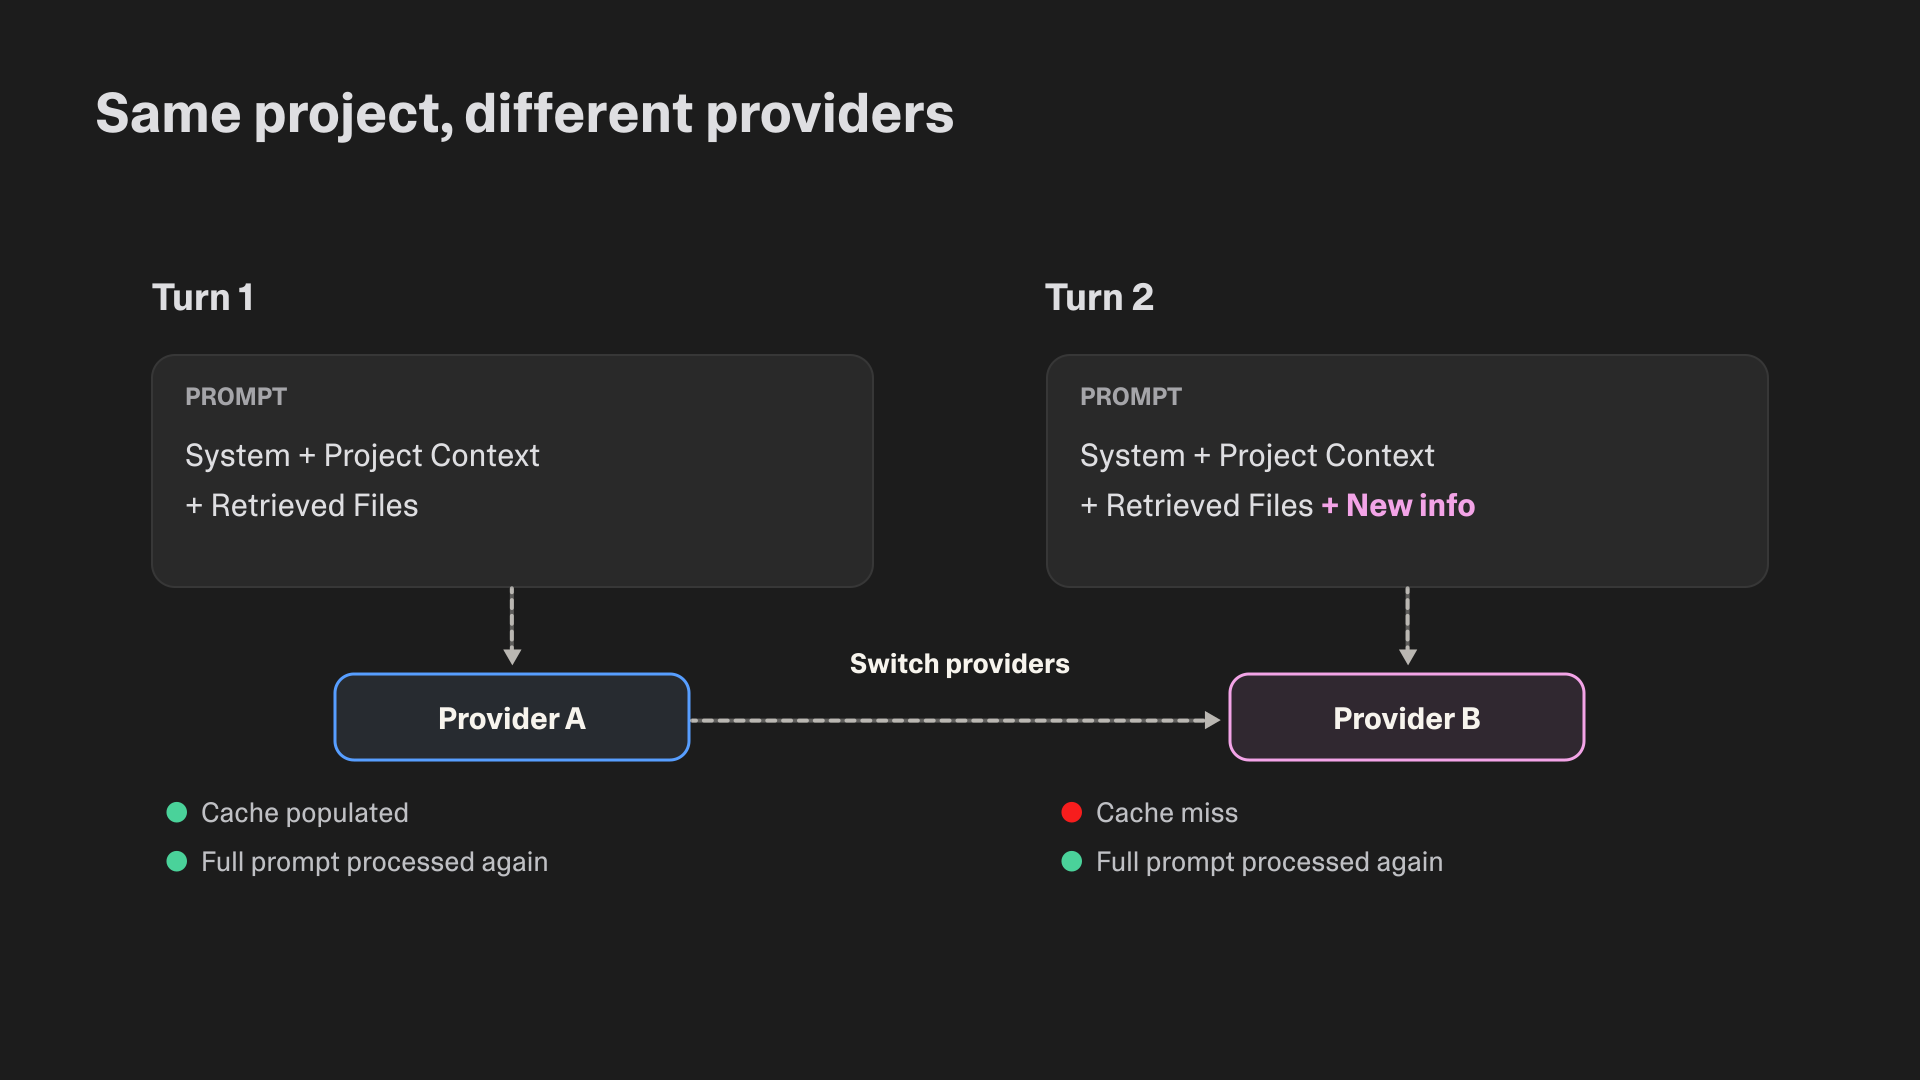
This is inefficient and expensive, but it gets worse. The rate limits that LLM providers impose on us are primarily defined in terms of the number of non-cached tokens that we send them, so if we do a poor job here, we could deplete all our capacity across all providers, meaning we'd have to rate-limit our users.
To prevent that from happening, simple fallback chains (ordered lists of providers to try if a request fails) aren't enough. We need a form of load balancing that spreads traffic across providers so that each one stays within its capacity, while also keeping consecutive requests for the same project on the same provider as much as possible.
How it works: Multiple fallback chains and project-level affinity
To preserve prompt caching while still handling failures, we don't rely on a single global fallback chain. Instead, we generate multiple fallback chains with different providers as the first choice. Each project is assigned one of these chains and keeps it for a short window of time, so that consecutive requests for the project are routed consistently.
The fallback chains themselves are constructed probabilistically. Conceptually, the algorithm works like this:
- Start with a set of weights representing what fraction of the traffic each provider should receive.
- Sample the first provider in the chain, where the probability of picking each provider is proportional to its weight.
- Sample the second provider from the remaining providers, again proportional to their weights.
- Continue until all providers have been picked and we have a full permutation.
This gives us a space of possible fallback chains where providers with higher weights are more likely to appear earlier, but no provider appears more than once in a chain. Providers with zero weight are appended at the end in their configured order.
Choosing provider weights
When we first implemented load balancing, we set provider weights manually based on our understanding of capacity and our provider preferences. In practice, this turned out to be painful to maintain.
Different providers measure tokens differently. Some include cached tokens in their rate limits, and others don't, which makes it hard to compare stated limits directly. On top of that, provider capacity isn't static. Incidents happen, rate limits change, and effective throughput varies with traffic patterns.
When a provider started returning errors, we would have to manually reduce its weight to send less traffic its way. When conditions improved, we'd have to adjust it again. At Lovable, we have better things to spend our time on, so we decided to automate it.
We had a clear problem costing us time and money, so we built a dynamic solution knowing we could always rip it out if it didn't work.
Instead of managing weights by hand, the plan was to adjust them automatically based on data. In practice, this has two steps:
- Continuously calculating availability for each provider using a PID controller. A PID controller adjusts allocation using recent request outcomes. This lets us estimate how much of our traffic a provider can handle at any given time.
- Using that availability to calculate the weights. In this step, we incorporate our preferred order of providers into the calculation.
Calculating provider availability
To continually assess provider capacity, we assign each provider an availability that is initially set to 1, representing that the provider is healthy. Every 30 seconds, we compute a score for each provider based on recent traffic:
score = (number of successful responses) - 200 × (number of errors) + 1
We then use a PID controller to adjust the provider's availability, trying to keep this score close to zero. The factor 200 corresponds to a target of roughly 0.5% errors.
- If the score is negative (roughly, if the error rate rises above 0.5%), we reduce the availability so that the provider receives less traffic.
- If the score is positive, we increase the availability so that the provider receives more traffic.
- If we didn't use the provider at all, then the bias (the + 1) causes us to increase the availability slightly to prevent us from giving up on the provider forever, even if it failed previously.
- We cap availabilities to the range [0, 1].
Calculating provider weights from availability
At any given time, the sum of all provider availabilities will often exceed 1. This simply means that, in aggregate, providers can handle more traffic than we currently have. That gives us flexibility: Since we only need the weights to sum to 1, we can choose which capacity to maximize and which to underutilize.
We work off of our preferred order of providers (the order in which we would ideally send traffic to providers, due to observed speed, model behavior, or operational requirements), and calculate weights as follows:
- For the first provider in the preferred order, the weight is its current availability.
- For the second provider, the weight is the minimum of its current availability and 1 - (weight of the first provider).
- For the third provider, the weight is the minimum of its current availability and 1 - (sum of weights of the previous providers).
- And so on.
This way, preferred providers are favored, with less preferred providers receiving first-choice traffic when others are at capacity.
If total availability is below 1, we scale the weights up proportionally so that they still sum to 1. If all availabilities are zero, we use equal weights. This keeps requests flowing, but it cannot create capacity: providers can still return errors when demand exceeds what they can serve.
We sample a fallback permutation using these weights and cache that permutation for the project. For the next few minutes, that project will keep using the same fallback chain, which preserves prompt caching across turns.
Wrapping up
The system described here grew out of fairly specific constraints: we needed to spread traffic across multiple LLM providers while taking into account both our preference between different providers and the providers' fluctuating capacities, all without constantly switching providers for the same project.
Using multiple fallback chains with project-level affinity gives us a way to preserve the benefits of prompt caching. By automatically re-weighting providers based on live traffic, the system can maximize capacity at preferred providers and back off smoothly when errors appear. In practice, this means that we need less manual tuning and can keep serving requests during some provider problems.
This is one example of the kind of infrastructure challenge we tackle every day at Lovable. Personally, seeing the system smoothly redistribute traffic during a provider incident, without anyone having to intervene, was truly satisfying.
To make the load balancer behavior easier to explore, we used Lovable itself to build a simulator app. It allows you to experiment with provider capacity and failure scenarios and see how fallback chains, weights, and stickiness interact over time.
If building systems like this sounds exciting, we'd love to hear from you. We're a small, fast-moving team where engineers own problems end-to-end, from identifying the issue to shipping the fix to production. There's plenty more to figure out, e.g. automatically rerouting traffic to other providers when a provider becomes slower than usual. Take a look at our open roles.